Federated Learning
Distributed machine learning that coordinates model training across data holders without centralising their raw records.
- Revision
- 1
- Created by
- SCIENDIA Knowledge Desk
- Updated by
- SCIENDIA Knowledge Desk
- Last updated
- 18.08.2026 11:13
Built by the community
Members can improve this article. Every saved change remains visible in the revision ledger.
Overview
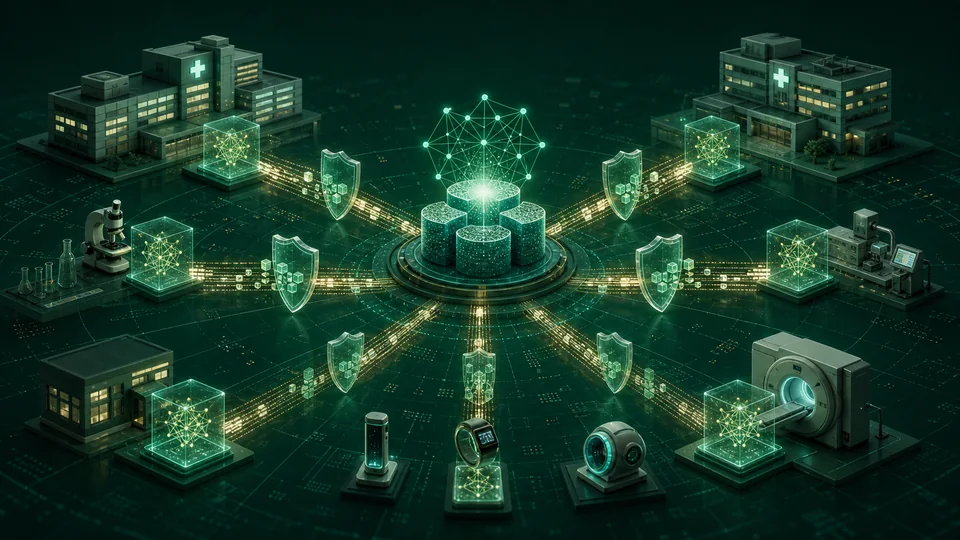
Federated learning trains a shared model by sending computation to hospitals, organisations or edge devices that retain local data. Participants calculate parameter updates or sufficient statistics, and a coordinating service aggregates those contributions into a new global model across repeated communication rounds.
Technical foundations
Federated optimisation minimises an objective assembled from local empirical risks without pooling records. Federated averaging distributes current parameters, performs stochastic local updates and aggregates client models in proportion to selected weights. Multiple local steps reduce communication but create client drift when feature and label distributions differ. Proximal penalties, control variates and adaptive server optimisers address this heterogeneity. Cross-device settings involve millions of intermittently available clients, whereas cross-silo settings use a smaller number of stable institutions with larger datasets and stronger contractual governance. These regimes require different algorithms and security assumptions.
How it works
A typical round selects clients, distributes a model, performs several local optimisation steps and combines weighted updates. Secure aggregation can hide individual contributions from the coordinator, while differential privacy bounds selected leakage. Personalisation layers, clustered models or meta-learning address populations whose data distributions differ substantially.
Measurement and research methods
Evaluation should partition clients rather than randomly mixing their records across train and test sets. Reports include global and worst-client performance, calibration, communication bytes, energy, participation rate and convergence under dropout. Secure aggregation uses cryptographic masking so the server learns only a sum once enough clients contribute. Differential privacy clips and noises updates to bound selected individual leakage, with a declared privacy budget and accounting method. Red-team tests examine membership inference, gradient reconstruction, poisoning and backdoors. Authentication, signed software, reproducible training logs and rollback procedures protect the broader system beyond model aggregation.
Key ideas
- Keeping raw data local does not by itself guarantee privacy or regulatory compliance.
- Non-identically distributed client data can destabilise optimisation and disadvantage minority sites.
- Threat models must cover malicious participants, poisoned updates and an untrusted coordinator.
Current research frontier
Research develops personalised federated models, asynchronous protocols and compression for low-bandwidth devices. Split learning divides a network between client and server, while federated analytics computes aggregate statistics before model development. Robust aggregation seeks to tolerate malicious updates, but defences can fail when benign populations are highly diverse. Foundation-model adaptation introduces large parameter and memory costs, motivating low-rank updates and selective fine-tuning. Governance remains a technical frontier: institutions need enforceable purposes, deletion policies, audit access and benefit sharing. Local storage reduces one risk surface but does not prove fairness, privacy or lawful processing by itself.
Why it matters
Federated learning enables cross-institutional research and on-device intelligence when data movement is restricted by privacy, sovereignty, bandwidth or commercial boundaries. It can also support continuous improvement from decentralised real-world use.
Limits and open questions
Model updates may leak information unless protected, and cryptographic safeguards add computation and communication cost. Client dropout, unreliable networks, unequal hardware, changing populations and weak governance can reduce both accuracy and accountability despite decentralised storage.
Explore through connected concepts
This article is indexed with 20 technical tags. Select a tag to explore the Wiki by concept.
You may also explore
Recommended from the technical tags shared with this article.

Artificial Neural Networks
Layered computational models that learn distributed representations by adjusting weighted connections from data.
Read article →